AI Credibility: From GxP Evidence to FDA Decisions (FDA DRAFT Guidance Jan2025)
Explore AI credibility in life sciences and how GxP validation evidence can become a connected, defensible argument for FDA regulatory decisions involving AI models.
1.0. Introduction
Imagine an FDA reviewer looking at an AI-supported analysis in a drug or biologic submission.
The model has been validated. The organization has completed an AI risk assessment. Testing is documented. Controls are established. Monitoring is in place.
Then comes a simple question:
“Why should we rely on this AI output for this decision?”
That question is harder to answer than “Was the AI validated?”
And it points to an important shift in AI credibility for life sciences.
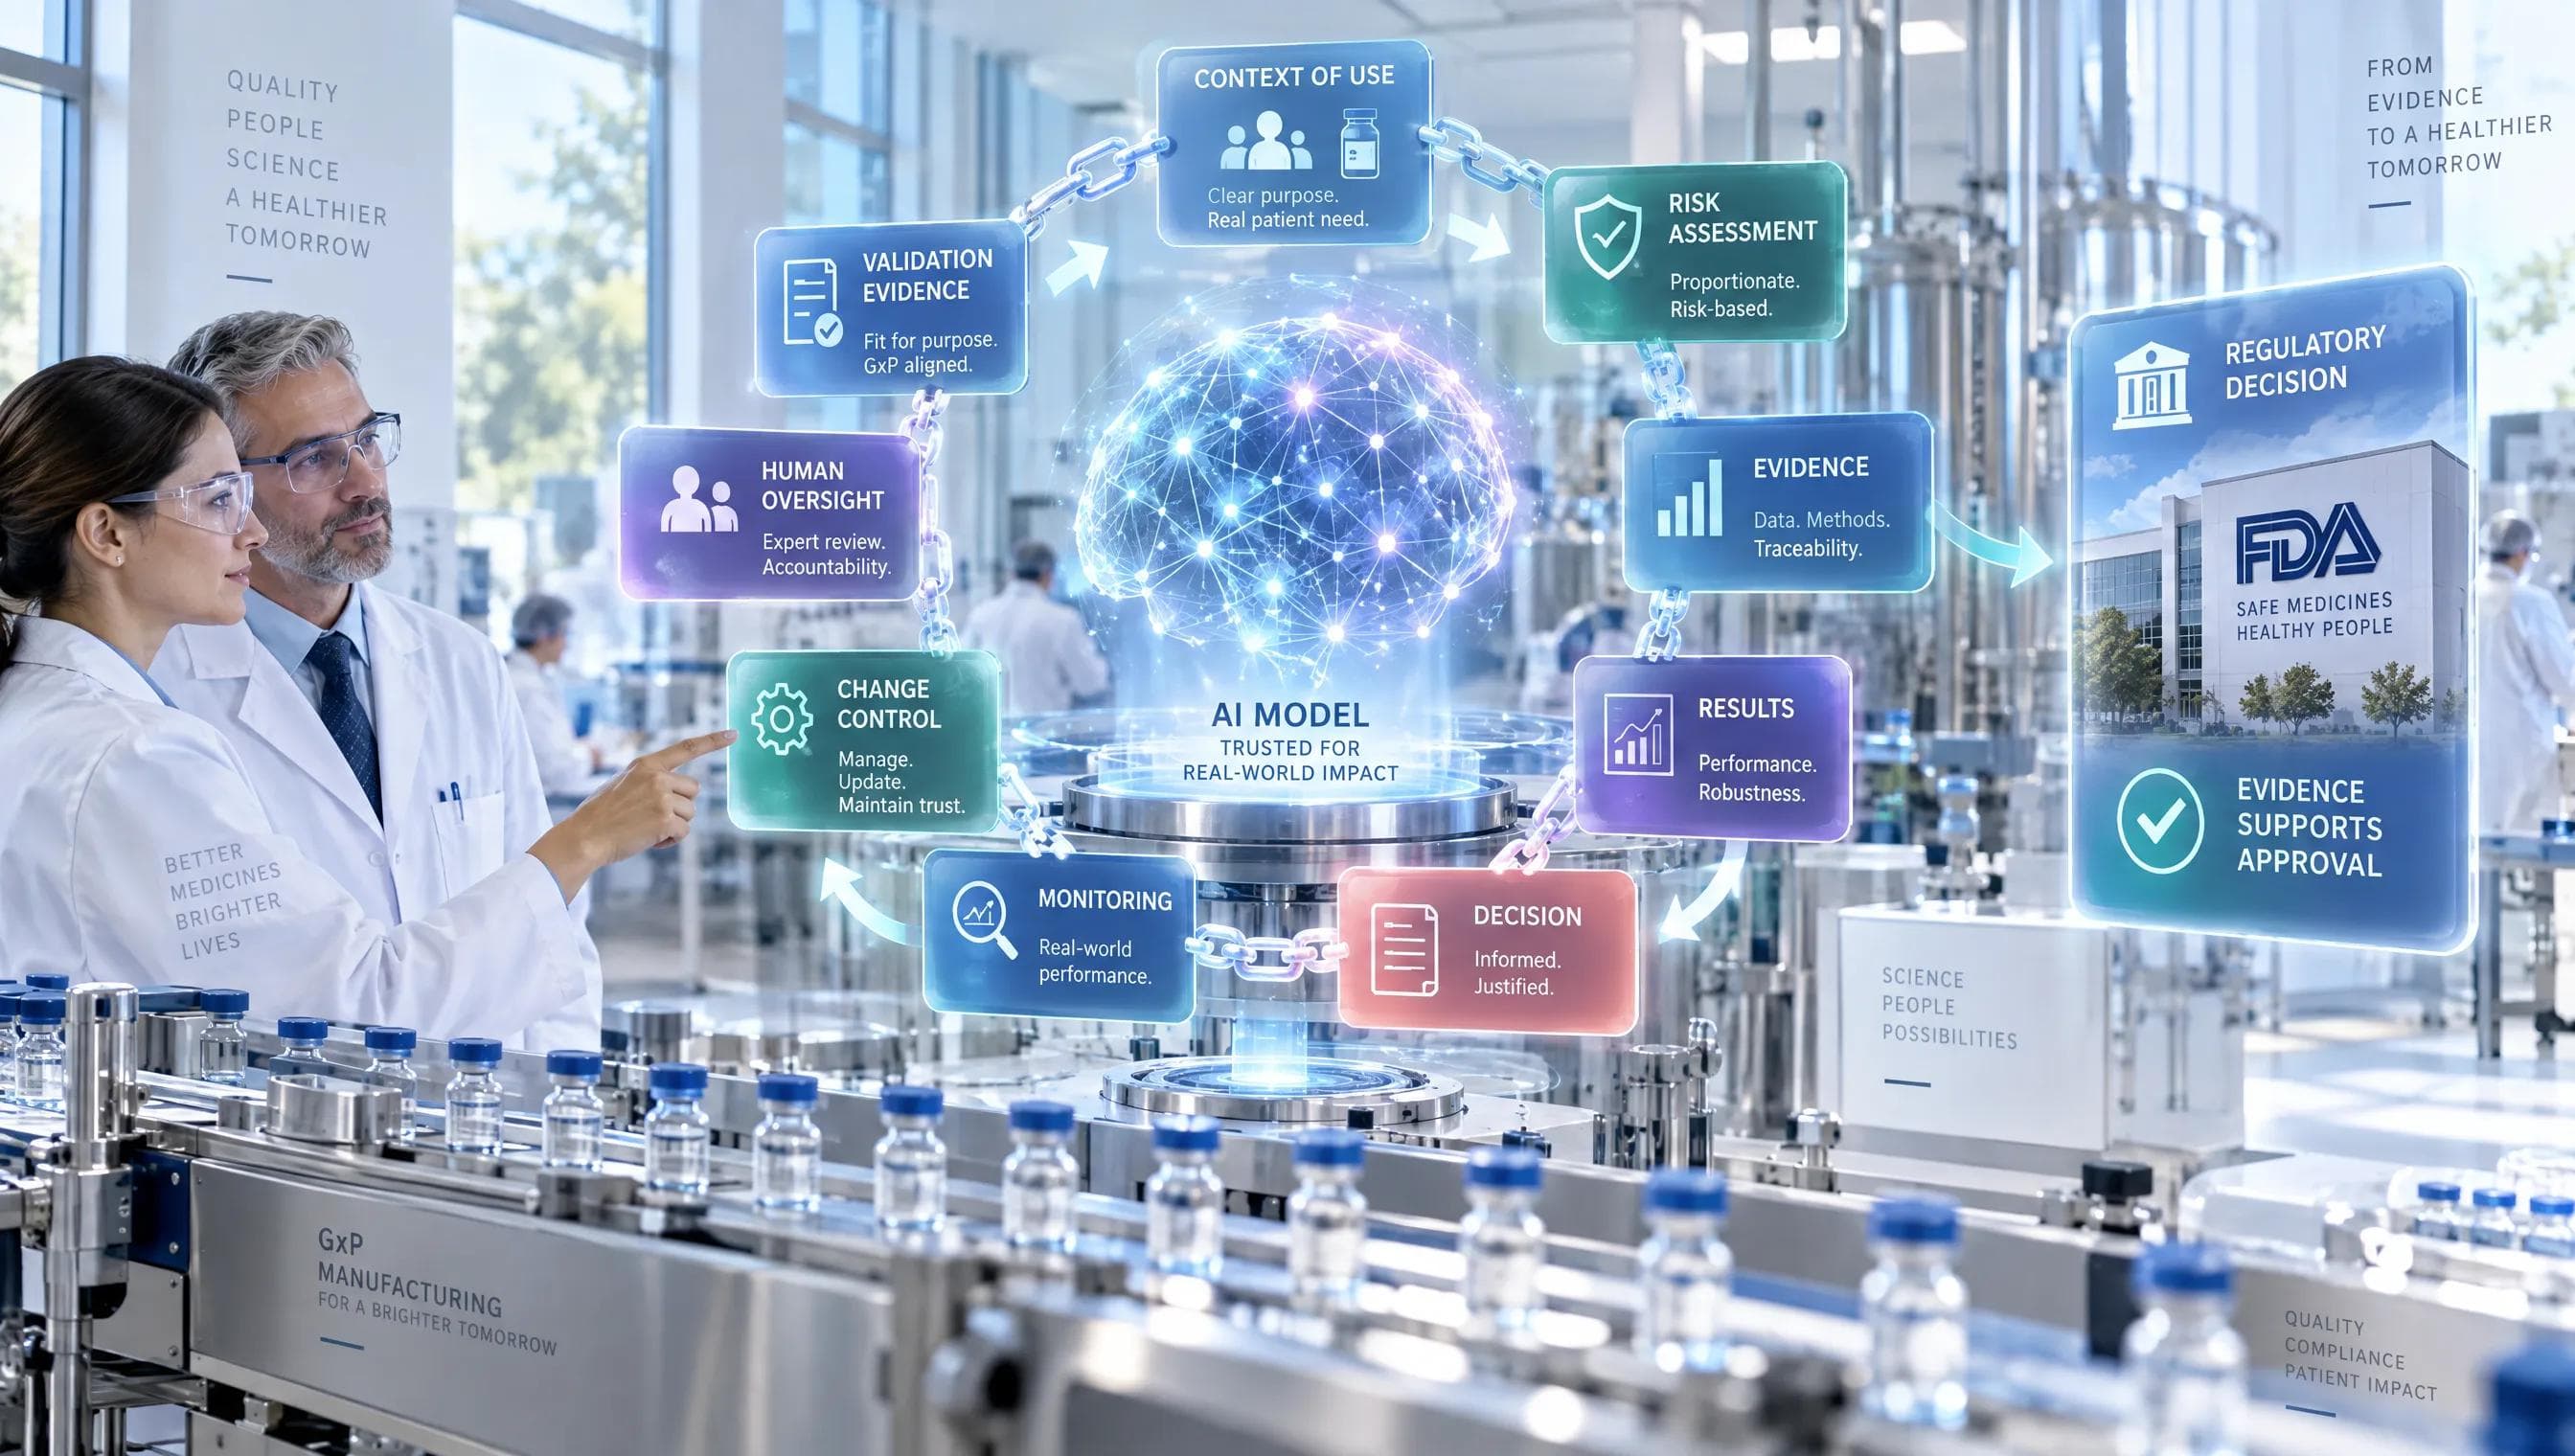
The FDA’s January 2025 draft guidance introduces a risk-based approach for assessing the credibility of AI models used to support regulatory decisions involving the safety, effectiveness, or quality of drugs and biological products. At the center of that approach is the Context of Use (COU), the specific role and scope in which an AI model addresses a defined question of interest.
This does not make existing GxP AI validation controls obsolete. It makes them more valuable. The next challenge is connecting those controls into something more meaningful, a defensible AI evidence argument for a specific regulatory decision.
2.0. AI Credibility: The Gap Between Validation and Decision Evidence
For years, the central question around computerized systems has been familiar:
Is the system validated for its intended use?
With AI, that question remains necessary. But it is no longer sufficient.
Consider two uses of AI.
In the first, an AI application analyzes manufacturing deviations and helps quality professionals identify records that deserve additional attention. In the second, an AI model prioritizes potential safety signals that may influence a regulatory assessment.
Both applications may be validated. Both may have documented testing. Both may operate within controlled GxP environments.
Yet the evidence needed to justify reliance cannot automatically be assumed to be the same. Because the consequence of the decision is different, the role of the AI is different, and the level of reliance on its output is different. That is the AI credibility gap.
“Credibility is not a property of the model. It is a conclusion supported by evidence for a defined use.”
The FDA’s approach reflects this principle by connecting AI model credibility to a specific Context of Use rather than treating credibility as a universal characteristic of the model.
This changes the conversation from AI model validation to decision evidence.
The model is no longer evaluated in isolation. Organizations must explain what the model is being used to answer, how its output influences the decision, what could happen if it is wrong, and whether the available evidence supports appropriate reliance.
That is a much more useful way to think about AI regulatory compliance.
3.0. Context of Use: The Foundation of AI Credibility
Here is where the conversation changes.
A Context of Use (COU) defines the specific role and scope of an AI model in addressing a question of interest. Put simply, it answers,
What exactly are we asking this AI to do, and under what conditions will we rely on its answer?
Imagine a biotech company using AI to review batch records.
The AI identifies unusual patterns and flags 5% of batches for human review. In this situation, the AI supports the quality team. Its output triggers additional investigation, but it does not independently determine batch release.
Now change one element. Suppose the organization decides that the AI output will become the sole basis for determining which batches can proceed to release.
The underlying model has not changed. The software has not changed. The model may have the same training data and the same technical architecture.
But the Context of Use has changed.
“The model has not changed. The decision context has. And therefore, the evidence required changes as well.”
This is why COU should become an organizing principle for AI validation and regulatory evidence.
An advisory AI model, an AI model that materially influences a decision, and an AI model whose output effectively determines a decision can require different levels of credibility evidence. The important question is therefore not simply whether an AI model is “validated.”
It is whether the validated boundaries of the model match the decision in which its output will be used.
4.0. AI Risk Assessment Determines Evidence Depth
This leads to a second shift. Not every AI application requires the same depth of AI credibility assessment.
A practical risk filter starts with two questions:
How consequential would the decision be if the AI were wrong?
And
How much does the decision depend on the AI output?
Return to the batch-record example. If AI identifies records for human review, trained reviewers can examine the underlying documentation before making the final decision. Additional information can provide corroborating evidence.
The AI matters, but the decision does not depend on the model alone. Now remove the human review and make the AI output determinative.
The risk profile changes. This means AI assurance cannot focus only on improving model performance. Organizations also need to consider how the overall decision process limits inappropriate reliance.
“Credibility is not achieved by making the AI smarter. It is achieved by designing the decision system so that inappropriate reliance is constrained.”
Human oversight, corroborating evidence, defined operating boundaries, and controlled decision processes can all influence how AI credibility is established.
This creates a more realistic approach to GxP AI governance. Credibility belongs to the relationship between the AI model and the decision not to the model alone.
Want to learn more about xLM Continuous Intelligence?
5.0. AI Evidence: From Documentation to a Credibility Argument
Here is where many organizations stumble. They have evidence. Sometimes they have a lot of it.
There may be AI validation records, risk assessments, test documentation, change records, monitoring records, approvals, and procedures. Yet when someone asks why an AI output can be trusted for a particular decision, the answer becomes a document hunt.
That is the missing layer.
“A credibility case is an argument, not a document collection.”
A strong AI credibility assessment begins with the question of interest.
What exactly is the organization asking the AI to help answer?
From there comes the Context of Use. What role does the AI play in answering that question? What is inside the approved boundary, and what is outside it?
Then comes risk.
What could happen if the AI produces an incorrect result? How much influence does that output have on the final decision?
Only then can the organization determine what evidence is necessary to establish appropriate credibility. That evidence is executed under controlled conditions. The organization evaluates the results and documents relevant deviations or limitations. Finally, it reaches a conclusion about whether the AI model is adequate for the defined Context of Use.
The evidence chain moves from the question, to the context, to the risk, to the evidence, to the result, and ultimately to the decision.
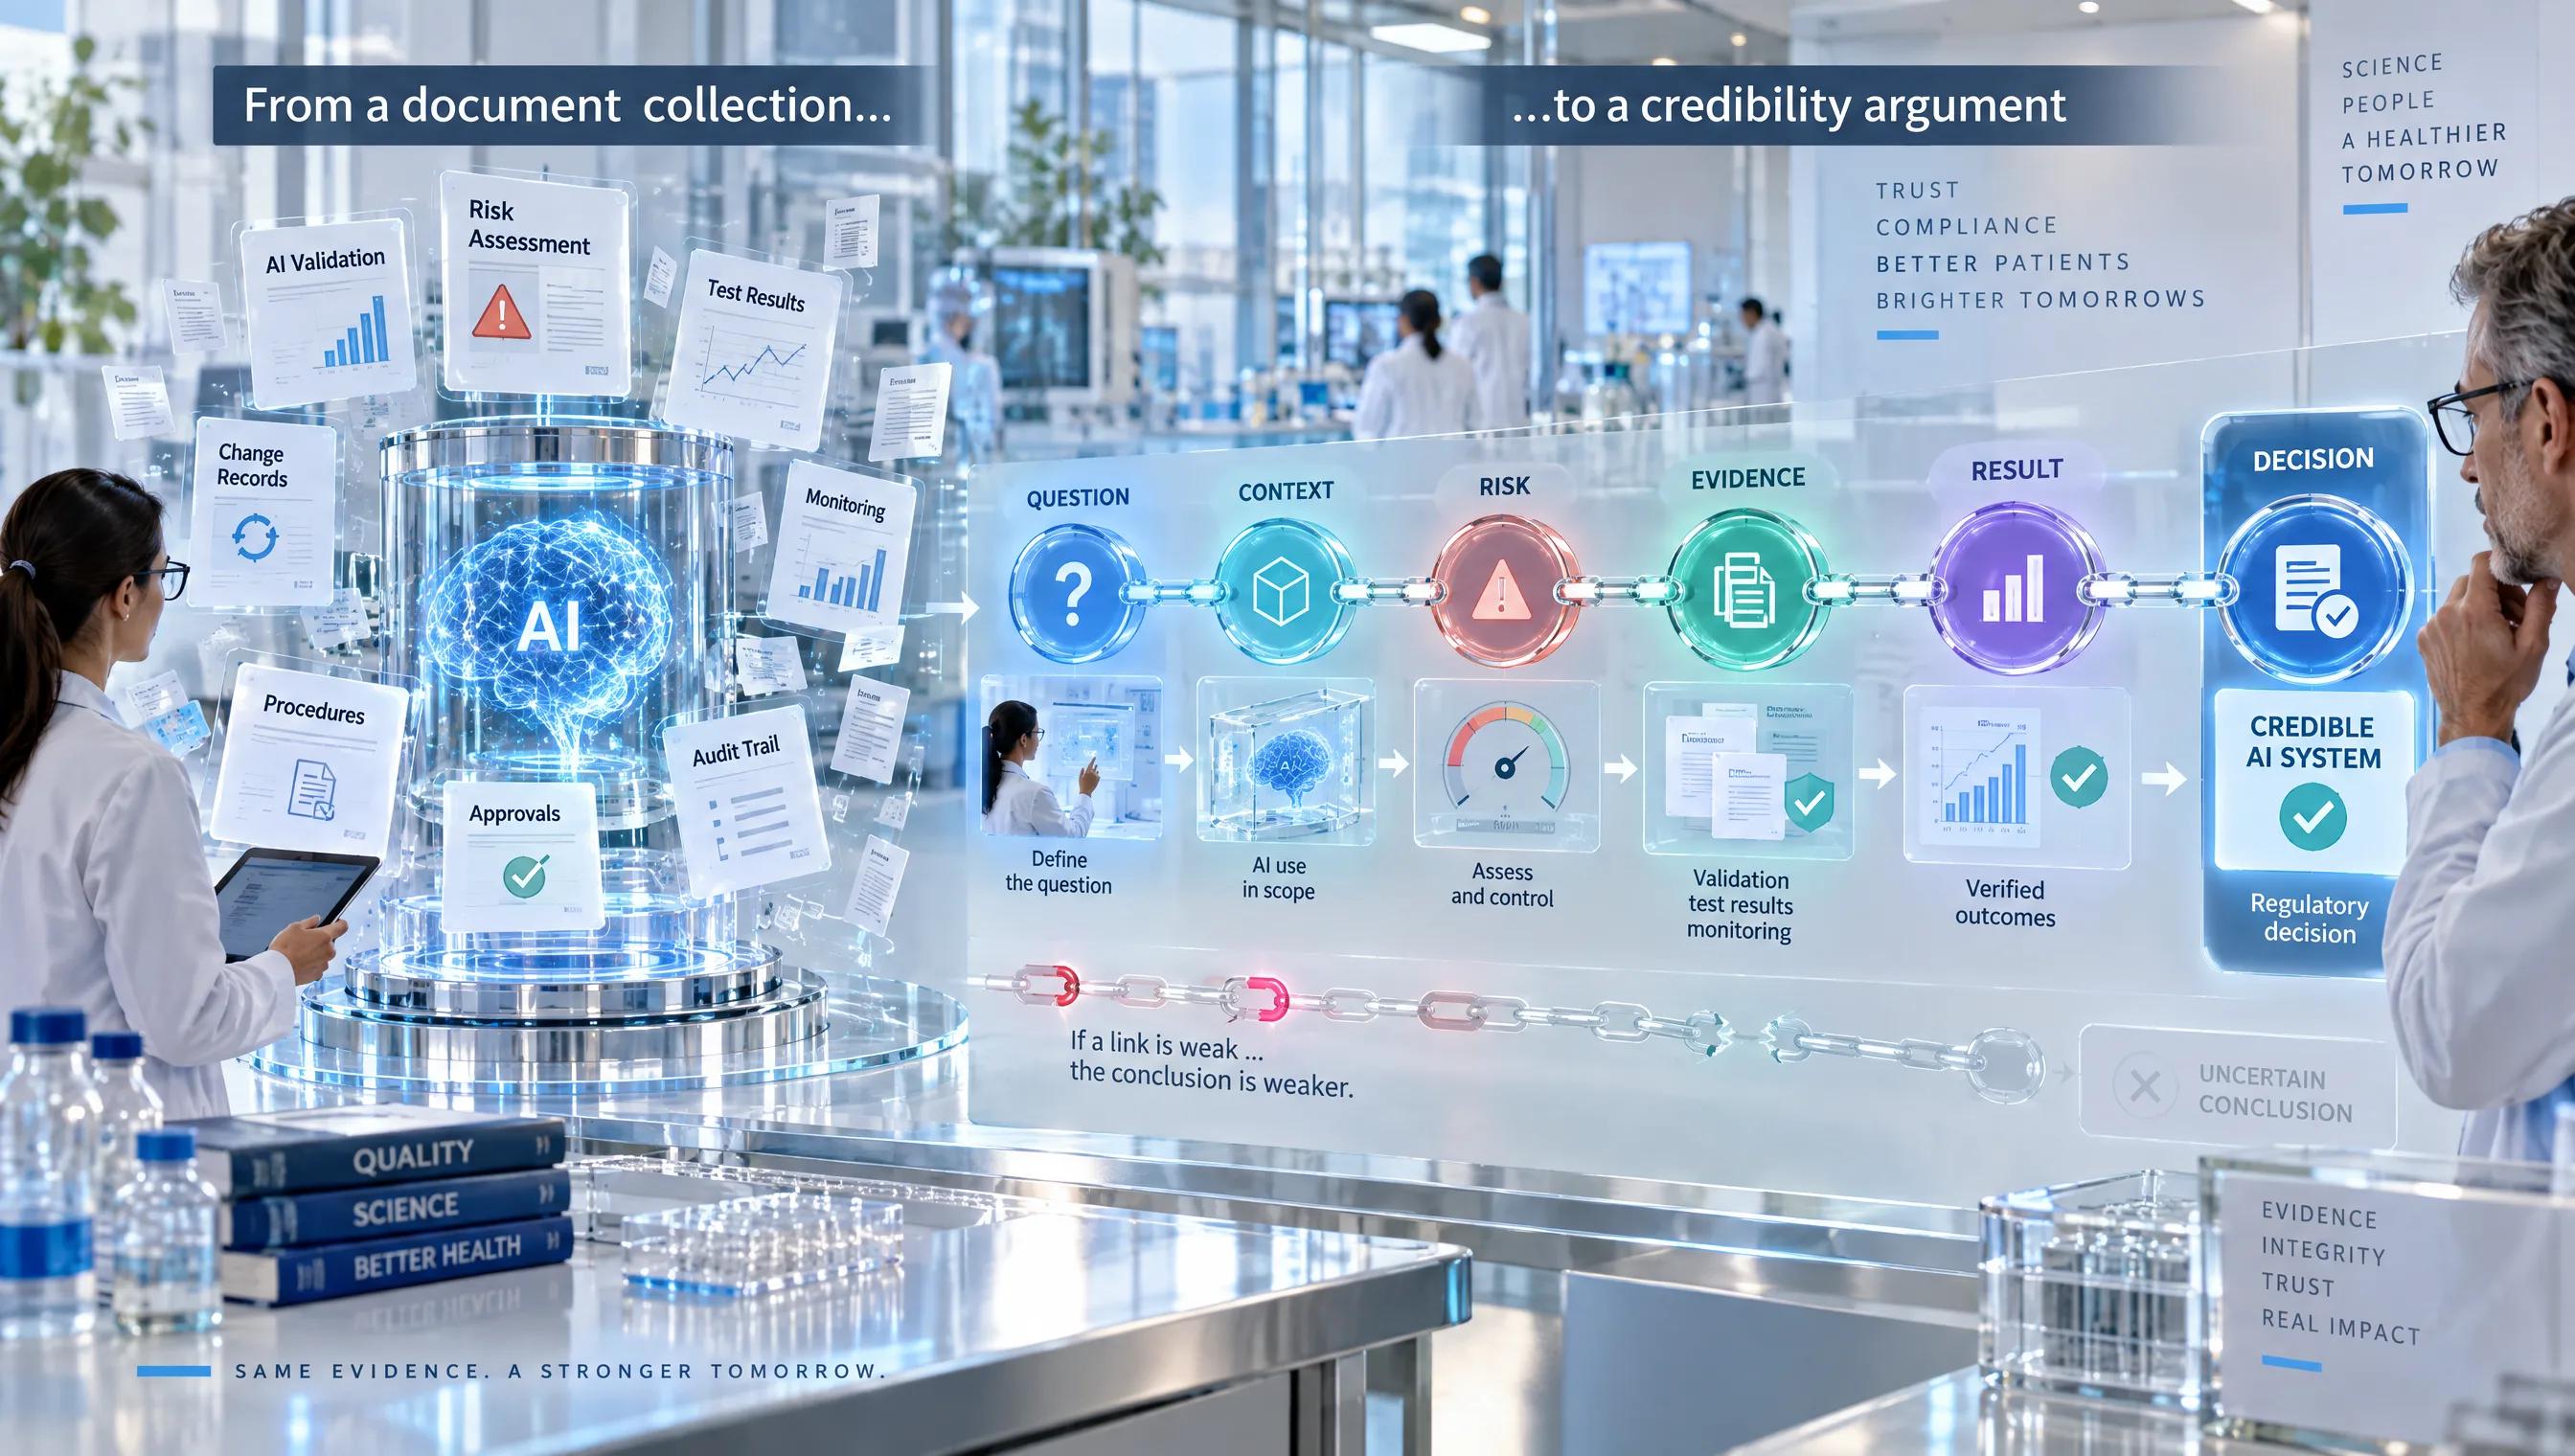
If the question is unclear, the Context of Use becomes unclear. If the context is unclear, the risk assessment becomes difficult to justify. If the risk is poorly understood, the evidence strategy may be inadequate.
And if the evidence cannot be connected back to the decision, the final AI credibility conclusion becomes difficult to defend. The goal is therefore not more documents. It is a more connected argument.
6.0. AI Evidence Lineage: Building a Credibility Graph
Now imagine an organization with one AI application. Connecting its intended use, risk assessment, testing, and evidence may be manageable.
Now imagine twenty AI applications across drug development, manufacturing, quality, and safety.
The problem changes. This is where AI evidence lineage becomes important. Think of it as a family tree for every AI-supported decision.
You should be able to trace a decision backward to the AI output, the evidence supporting that output, the assessment under which the evidence was generated, and the Context of Use that defined why the model was being relied upon.
“The question is no longer ‘Where is the evidence?’ It is ‘What does this evidence support, and what changed since it was generated?’”
This becomes particularly important as organizations expand from individual AI applications to portfolios of AI systems and agents.
A credibility graph does not replace controlled documentation. It connects it.
It allows an organization to understand which evidence supports which conclusion and whether a change somewhere in the chain affects the credibility of a decision downstream.
That is the difference between having evidence and being able to explain the evidence.
7.0. AI Credibility Boundaries and Lifecycle Impact
The final piece is lifecycle impact. An AI credibility conclusion needs a boundary.
If an AI model was assessed for a particular population, operating condition, model version, configuration, and decision role, an organization should not automatically extend that conclusion to a materially different use.
Consider the batch-record example again. The organization updates the AI model. The new version behaves differently for certain types of records.
The original model was thoroughly validated. The original evidence still exists. The original reports remain approved.
But does that evidence automatically establish credibility for the new version?
Not necessarily.
The organization needs a way to determine whether the change affects the original AI credibility assessment.
That may require additional assessment, or it may demonstrate that the existing evidence remains applicable. The important point is that the organization can explain the basis for that conclusion.
This is where change control becomes more than an operational compliance activity. It becomes a mechanism for preserving the validity of the original credibility argument.
The same principle applies when the Context of Use changes. If an AI model moves from advisory use to a decision-making role, the original evidence may no longer answer the new credibility question.
The model may be identical. The decision is not. That distinction is central to sustainable AI regulatory assurance.
8.0. From GxP AI Validation to Decision Evidence
The opportunity is not to create another isolated compliance exercise every time AI guidance evolves.
It is to connect the work organizations are already doing.
The controls discussed through the EU Annex 22 perspective establish an important foundation for controlled AI use in GxP environments. The FDA credibility framework takes that conversation into a more specific space,
Can the available evidence establish appropriate trust in an AI model for a defined regulatory use?
The answer cannot come from a single validation report. It comes from the relationship between the question, Context of Use, risk, evidence, results, decision, and lifecycle controls.
That is the next step in AI governance for life sciences.
This is also where platforms such as xLM’s Continuous Intelligent Validation (cIV) can provide a practical foundation. Rather than treating validation documents as isolated outputs, cIV is designed to connect activities across the validation lifecycle from requirements and risk assessment through test planning, execution, traceability, and approval.
The value of this approach is not simply generating documents faster. It is creating a more connected evidence trail in which requirements, testing, results, and approvals can be traced back to the intended use of the system. For AI-enabled applications, that type of traceability can help organizations build the underlying evidence structure needed to evaluate credibility as the Context of Use, risk, or system configuration evolves.
The technology does not replace the credibility judgment.
It helps make the evidence supporting that judgment more connected, traceable, and reviewable.
Organizations can start with one practical exercise, take one AI use case and ask whether they could clearly explain why the available evidence is sufficient for decision the AI supports.
If the answer is unclear, the problem may not be a lack of documentation. It may be a lack of evidence architecture.
“The objective is no longer to prove that an AI system was controlled when deployed. It is to maintain a defensible answer to a harder question, Why should this output be relied upon for this decision?”
That is the shift from compliance evidence to decision evidence. And as AI becomes more deeply embedded in regulated drug and biologic development, that may become one of the most important disciplines in AI assurance.
9.0. References
Want to learn more about xLM Continuous Intelligence?
About the Authors
About Nagesh Nama
Nagesh Nama is the Founder and CEO of xLM Continuous Intelligence and ValiMation, bringing nearly 30 years of experience in AI-driven GxP compliance, computer system validation, and regulatory technology for the life sciences industry. A recognized thought leader, he pioneered the industry's first Continuous Validation platform supporting compliant IaaS, PaaS, and SaaS environments under 21 CFR Part 11 and Annex 11. His work focuses on advancing intelligent validation, AI-powered compliance, predictive maintenance, temperature mapping, and GxP AI agents to help pharmaceutical, biotechnology, and medical device organizations accelerate digital transformation while maintaining continuous compliance. Nagesh is a member of the Forbes Technology Council and the Fast Company Executive Board, a contributor to Forbes and Fast Company, and has been featured by Microsoft for his work in AI agents.